Evaluating a Lucid AI model: measure the task, not the demo
Create a small, repeatable evaluation set for faithful summaries, structured extraction, uncertainty handling, and operational fit.
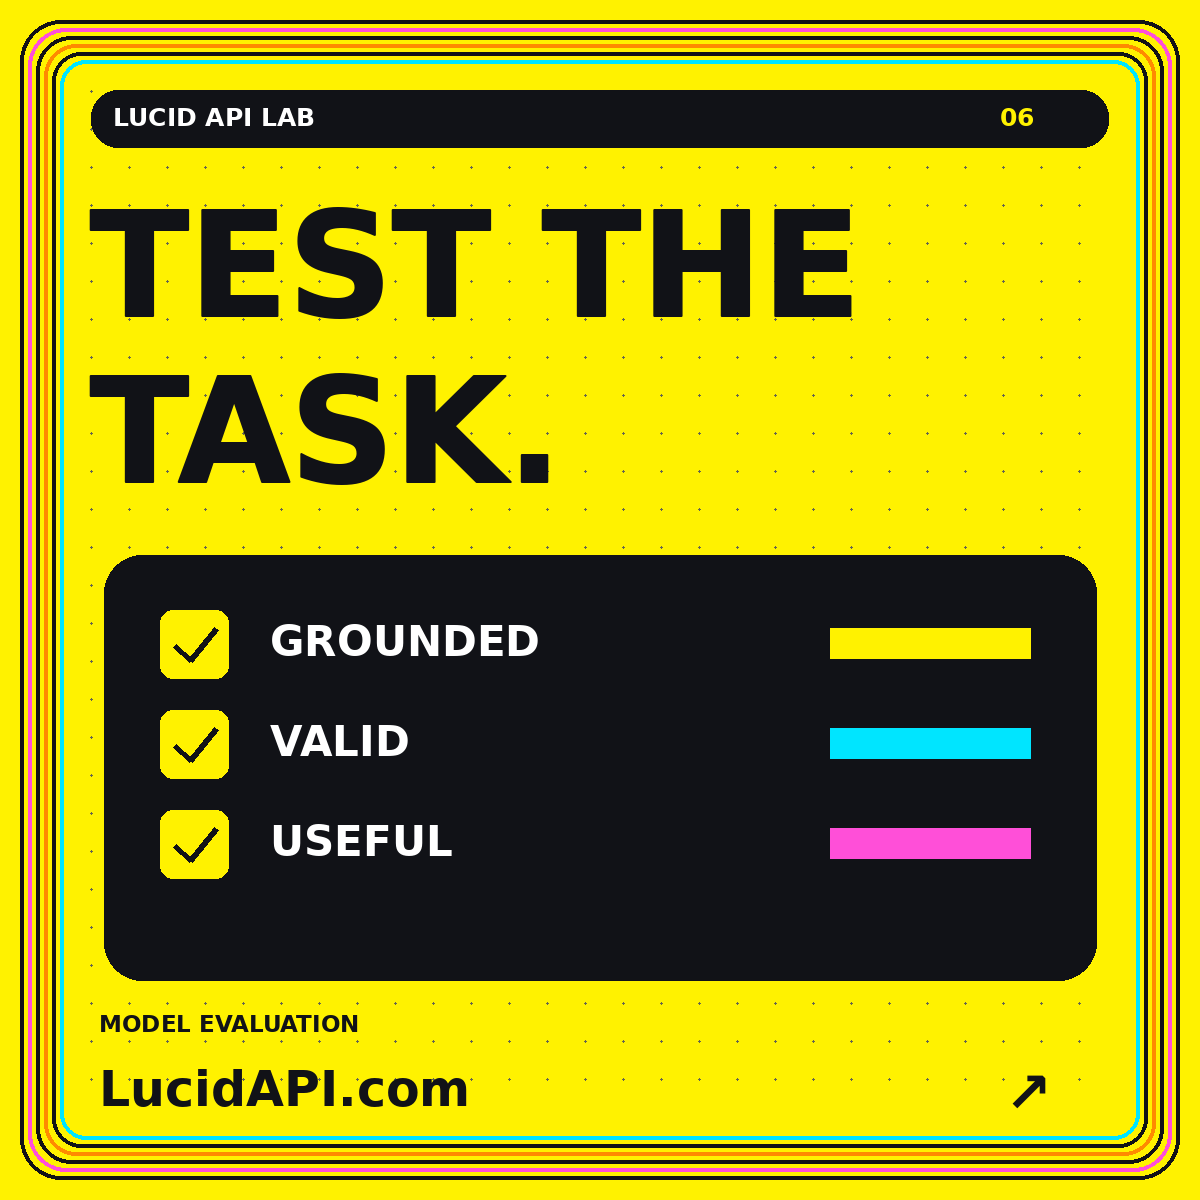
06 / TASK-LEVEL EVALUATION
Choose a model configuration by its behavior on your application’s actual task: faithful content, useful uncertainty, valid structure, and operational fit.
Define acceptance
Keep held-out cases
Record configuration
The Lucid AI Model topic is about evaluating models for lucid dream and agent-related workflows. It does not describe a proprietary LucidAPI.com model, published weights, or a benchmark result. Start by defining the operation your application needs and what makes its output acceptable.
For a summary task, useful requirements include preserving reported details, retaining meaningful uncertainty, and avoiding unsupported additions. For structured extraction, add field-level requirements and clear handling of absent information. For tool selection, evaluate the proposed action and its permission boundary as well as the final answer.
Create synthetic examples covering ordinary inputs and meaningful edge cases: short fragments, long accounts, uncertain names, changed source revisions, and text that resembles an instruction. Record why each example exists. Several output phrasings may be acceptable, but they should satisfy the same factual and structural constraints.
Separate examples used for prompt development from held-out cases used for comparison. Otherwise, repeated tailoring can make a familiar test set look more informative than it is. Preserve the tested inputs, outputs, and review decisions so the next run has a useful baseline.
Report unsupported details, omissions, uncertainty loss, invalid structure, and task drift separately. A polished sentence should not hide a serious grounding failure. Use explicit release criteria for unacceptable sensitive claims or actions outside the permitted task rather than averaging them into a broad quality impression.
Record the model identifier, task instruction, generation settings, context selection, output schema, and validation behavior. Changing any of these may affect the outcome. A new model and a revised prompt are not the same experiment, even if the final screen looks similar.
Keep operational measures alongside content review: elapsed time, attempts, resource use, and the frequency of accepted results. A configuration can produce useful text while remaining unsuitable for a particular interaction budget. Conversely, a low per-call cost is not enough when many results require repair or rejection.
Write down the tested task, the size and composition of the evaluation set, observed failures, and accepted limitations. A team can support a narrow language or input type while gathering evidence for broader use. Do not turn a small internal evaluation into a claim of universal superiority.
The long-form evaluation guide develops this process in detail. Pair it with Lucid AI API for integration behavior and Lucid Agent Models when the selected configuration can influence tool use. Evaluate again when the task or configuration changes materially.
FROM THE LUCID API LAB
Create a small, repeatable evaluation set for faithful summaries, structured extraction, uncertainty handling, and operational fit.
Use a transparent hypothetical model to estimate inference, retries, review, storage, and multi-step workflow costs without invented vendor prices.
Separate extraction, summary, and reflection so generated text remains grounded in the account the user actually provided.